Jules
Barth

AI / MLOps Engineer

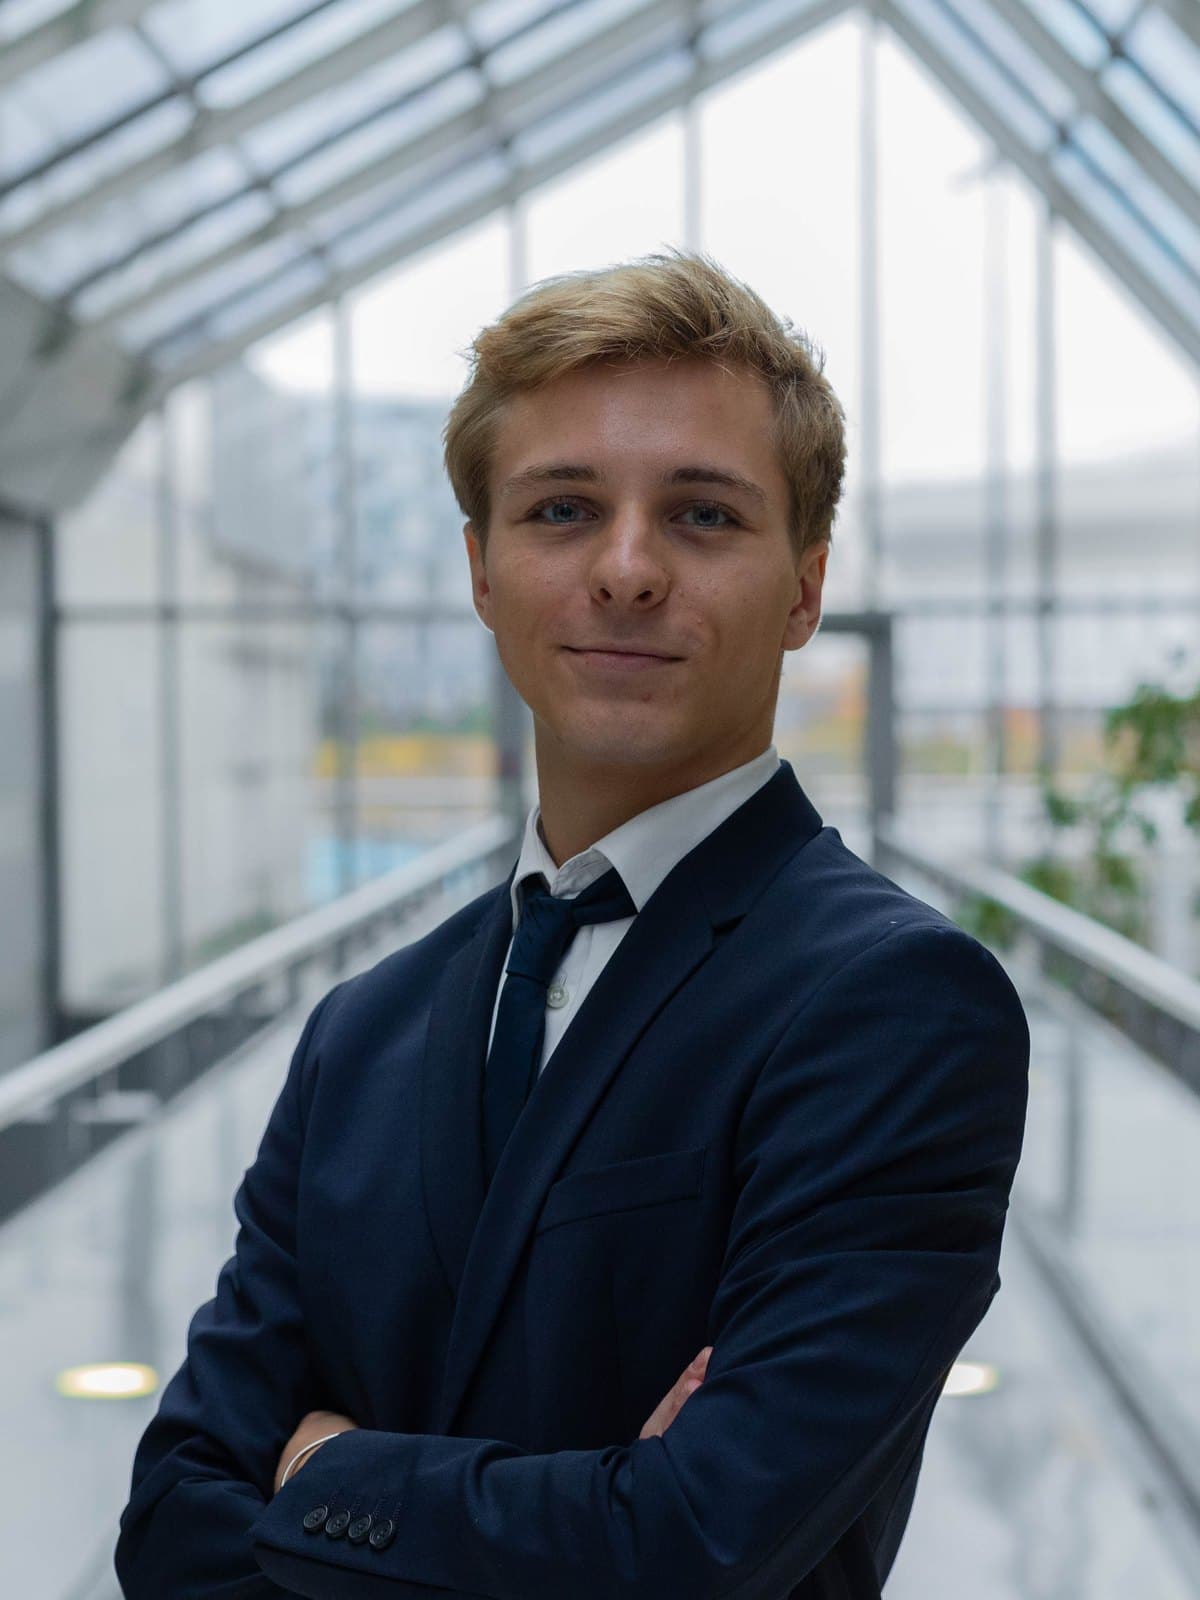
Portrait of Jules Barth in a suit, arms crossed, in a glass walkway.

I design and optimize AI systems for production.

MLOps internship at Safran AI · 3 open-source optimization projects. optimization, model compression, MLOps pipelines. (, ), compression and -based layer selection, end-to-end MLOps pipelines.

Available for a full-time role from November 2026.

Measured
verified result, with the machine and the method.
Limit
what does not work yet, stated plainly.

Three model-optimization projectsThree projects to make AI models lighter and fasterThree projects to make AI models lighter and faster

On the left, what the project claims. Right of the line, what is measured and what is not.

AKO

Automatically pick the fastest version of a computation, after checking that it is correct.Adaptive Optimizer. A validation tool for swapping computations in a language model.Adaptive Optimizer. A for swapping kernels in an .

AKO selection flow: five candidates go through an error-budget check, one is rejected, the others are measured, then the decision is cached.referenceF.rms_normtorch.compileTritontruncated Tritonbenchmarkcached decisionbudget (ulps)
Diagram of the flow, not a measurement. The truncated candidate stands for a kernel that is fast but wrong, rejected before it is measured.

An optimized computation is not faster everywhere, and it can be wrong without saying so. AKO tests each variant, drops the wrong ones and keeps the fastest.For each operation, , and , AKO tests the candidate (reference, fused , , ). It rejects those that fall outside an expressed in , measures the rest and caches the decision, with its reasons.

Measured
Checks that each version is correct before using it, and avoids up to a 55% slowdown compared with forcing the optimized version everywhere. Measured on a laptop.Picking the version per configuration avoids up to a 55% penalty ( forced) and 314% on ( forced). Against the best : 1.03× to 1.17× median. .Picking per avoids up to a 55% penalty ( forced everywhere, which loses on 22 of the 72 configurations) and 314% on ( forced everywhere). Against the best (almost always torch.compile): 1.03× to 1.17× median. Measured on an .
Limit
Covers three operations for now: about 1% effect on a full model.Three operations covered (≈ 24% of a 's time): overall impact ≈ 1%. In , 0.69× against the , cause under investigation.Three operations covered (≈ 24% of a 's time): overall impact ≈ 1%. In , 0.69× against the , cause under investigation.

· · · ·

QCompress

Compress a language model by factorization.Language-model compression by factorization, inspired by quantum computing. compression by decomposition, inspired by quantum computing.

A dense matrix is factorized into a chain of four small cores linked by ranks r1, r2, r3.dense WTT-SVDr1r2r3G1G2G3G4
How Tensor-Train decomposition works. The ranks are set by the recipe.

Automatically replaces the heavy layers of a language model with factorized versions, tracked in a real-time dashboard.TTLinear and TTEmbedding layers replace the dense layers of a model from a YAML recipe. A real-time dashboard tracks the metrics and compares the original model with the compressed one.

Delivered
Replacement is automatic; the compressed model can be exported and compared with the original.Automatic layer replacement, standard exports, comparison of the original and compressed models.Automatic layer replacement, , SafeTensors and export, FastAPI and Next.js dashboard.
Limit
Next step: measure and publish the compression ratio achieved.Next step: measure and publish the compression ratio achieved. Only one model family (GPT-2) for now.Next step: measure and publish the compression ratio achieved. Weights still rebuilt on the fly, GPT-2 family only.

· · · · FastAPI · Next.js

Q-GEOCompress

Make an aerial-image detector lighter, under quality control.Compression of an aerial detector, accepted only if the reliability thresholds pass.Post-training compression of an aerial detector, accepted only if the reliability pass.

Parameters removed: 0.34 % for plain SVD, 20.67 % for the data-aware pipeline. Both stay within the same quality thresholds.0 %10 %20 %Plain SVD−0.34 %Data-aware pipeline−20.67 %thresholds metthresholds met
Bars to scale, same quality thresholds for both methods.

Picks the layers to compress with a quantum-inspired optimization, and accepts the result only if the accuracy and reliability passes. on . The choice of layers to compress is encoded as a and solved with (, optional component, classical fallback), then factorized at low rank. The checks accuracy and before accepting a candidate.

Measured
A model 20% lighter, with 61 times more parameters removed than the standard method, while staying within the quality thresholds set.−20.67% parameters (data-driven rank allocation) versus −0.34% for the simple method, within the same quality thresholds. Accuracy (): 0.8007 versus 0.8943 originally.−20.67% parameters through Lagrangian rank allocation (data-aware), versus −0.34% for plain , within the quality thresholds set ( −0.10 max, CER@0.8 +0.02 max). mAP50 of 0.8007 versus 0.8943 at , 80-image test split, .
Limit
No speed gain measured on so far. The lighter model's speed is still to be measured, on too.No latency gain measured on for a lighter variant (−5.63% parameters): 96.0 ± 1.7 ms versus 98.8 ± 4.3 ms originally. Next step: measure the latency of the −20.67% model, then on .No latency gain measured on for the top-5 pareto-gain variant (−5.63% parameters): 96.0 ± 1.7 ms versus 98.8 ± 4.3 ms at ; the latency of the −20.67% model is not measured yet. Next steps: measure on , and plug this data-aware pipeline (still a study) into the gated chain.

· · · · ·

Also: RAG and LLM applications

I have also built assistants that answer from documents: search, , evaluation.End-to-end applications: retrieval, , evaluation.End-to-end applications: retrieval (), , evaluation.

  • Terros (HelloLeo)An assistant that finds more than 400 interface elements, so they are reused instead of rebuilt.Prototype assistant that finds more than 400 interface components, to encourage their reuse. prototype over more than 400 UI components to encourage their reuse.
  • HR FAQ Chatbot (DSPy)An HR question assistant for a fictional company: tuned model, document search, off-topic questions rejected, evaluation.HR assistant for a fictional company: tuned model, , document search, out-of-domain questions rejected.HR assistant for a fictional company: , optimization, , out-of-domain questions rejected, reproducible .Repo HR FAQ Chatbot (DSPy)
  • ESILV Smart AssistantAn assistant for the school, made of several : it answers questions and helps fill in forms. system: document search, form filling, coordination. system: , form filling, orchestration.Repo ESILV Smart Assistant

Other projects

  • qllm-pbitsPick a language model's words with a simulated network of random bits.Sample an 's with a simulated network.A network simulator that samples from an 's distribution ( on binary variables, one-hot penalty).Repo qllm-pbits
  • MistralTuneA platform to adapt a language model to your own data, in the cloud or locally.Mistral platform: cloud API or local training, job tracking, model comparison.Mistral platform: cloud API, local , job and dataset tracking, model comparison.Repo MistralTune
  • Sentiment Analysis with FHEAnalyze the tone of a text without ever decrypting the data. on data that stays encrypted end to end. under fully homomorphic encryption (): the data stays encrypted end to end.Repo Sentiment Analysis with FHE

Experience

My field: taking a model from experiment to production.My field: taking a model from experiment to production.

  1. April – September 2026

    MLOps Engineer (internship) — Safran AI

    Industrialized an MLOps platform: experiment tracking, model deployment, evaluation and monitoring, pipelines, integrated open-source tools such as , documented the platform.Industrialized an MLOps platform: experiment tracking, model deployment, evaluation and monitoring. Automated ML pipelines (, artifact management), integrated open-source tools such as , improved performance and reproducibility of ML workflows, documented the platform.

    Technologies: Python, SQL, PyTorch, TensorFlow, Scikit-Learn, ONNX, TorchScript, MLflow, Docker, Kubernetes, GitLab CI, GitHub Actions, AWS, Linux.

  2. April – August 2025

    Product Engineer — Terros (HelloLeo)

    Contributed to HelloLeo, a collaborative AI development assistant. Redesigned and launched the helloleo.dev website. Optimized model instructions (Claude, Gemini) and the multi-model architecture. prototype over more than 400 interface components.Contributed to HelloLeo, a collaborative AI development assistant. Redesigned and launched the helloleo.dev website (Netlify deployment, SEO and performance). Optimized model instructions (Claude, Gemini) and the multi-model architecture for consistent answers. prototype over more than 400 UI components.
  3. October 2022 – November 2024

    Technical Lead — SGN

    French federation of student esports associations: website development and maintenance, responsive design, performance optimization, technical documentation.French federation of student esports associations: website development and maintenance, responsive design, performance optimization, technical documentation and organization guidelines.

Other experience

  • Veni Vidi De Vinci student union: communications and events.
  • September 2021 – May 2022DevinciTrip (ESILV): vice-president of the student association.
  • Student jobs: customer service, restaurant work, private tutoring in maths and computer science.

Education

Trained at ESILV (engineering degree, Data & AI major), with a quantum computing track.

  1. Data Intelligence, AI & Quantum Track

    ESILV — Engineering degree (Master's level), Data & AI major

    Class of 2026. Quantum computing track: quantum algorithms, hybrid applications, post-quantum cryptography.Class of 2026. Quantum computing track: quantum algorithms, hybrid applications, post-quantum cryptography.

    Machine Learning, Deep Learning, Computer Vision · and generative AI · Big Data & Spark · BI pipelines and data analysis · Advanced quantum computing and applications · Post-quantum cryptography · Data Protection Management, Product Lifecycle Management.

  2. French scientific baccalaureate and American High School Diploma (dual diploma, 2020)

Languages: French (native), English B2 (TOEFL and Cambridge).

Skills

Python, , , , , , ,

Languages and data
Python, SQL, JavaScript, TypeScript, C++, C#, R, Spark, PostgreSQL, MySQL, MongoDB
AI and ML
, TensorFlow, Scikit-Learn, NumPy, Pandas, (Transformers), Ultralytics (YOLO)
LLMs and RAG
/ , , , Chroma,
Inference and GPU
, , , , , TensorRT
MLOps and deployment
, , , GitLab CI, GitHub Actions, AWS, pytest, Git, Linux, WSL2
Compression and quantum
, , , ,
Web
Next.js, React, Node.js, Vue.js, FastAPI, Pydantic, WebSockets

Get in touch

I am looking for a full-time AI or MLOps engineering role, starting November 2026.

julesbarth13@gmail.com

Outside code: rugby (11 years at RC Suresnes, then university rugby), skiing, climbing, snowboarding.

Level of detail